
AdsPower vs ClonBrowser: Which Anti-Detect Browser Wins?
Nov 18, 2026
Automated data collection replaces manual copying, typing, and spreadsheet maintenance with scripts, bots, APIs, and platforms that gather and organize information on their own. It is the backbone of modern analytics, AI training pipelines, and competitive research — and it is also where most teams hit their first real obstacle: websites that actively fight back against automated traffic.
This guide explains how automated data collection works, which tools fit which jobs, and how to keep collection running reliably when targets, platforms, and anti-bot systems push back.
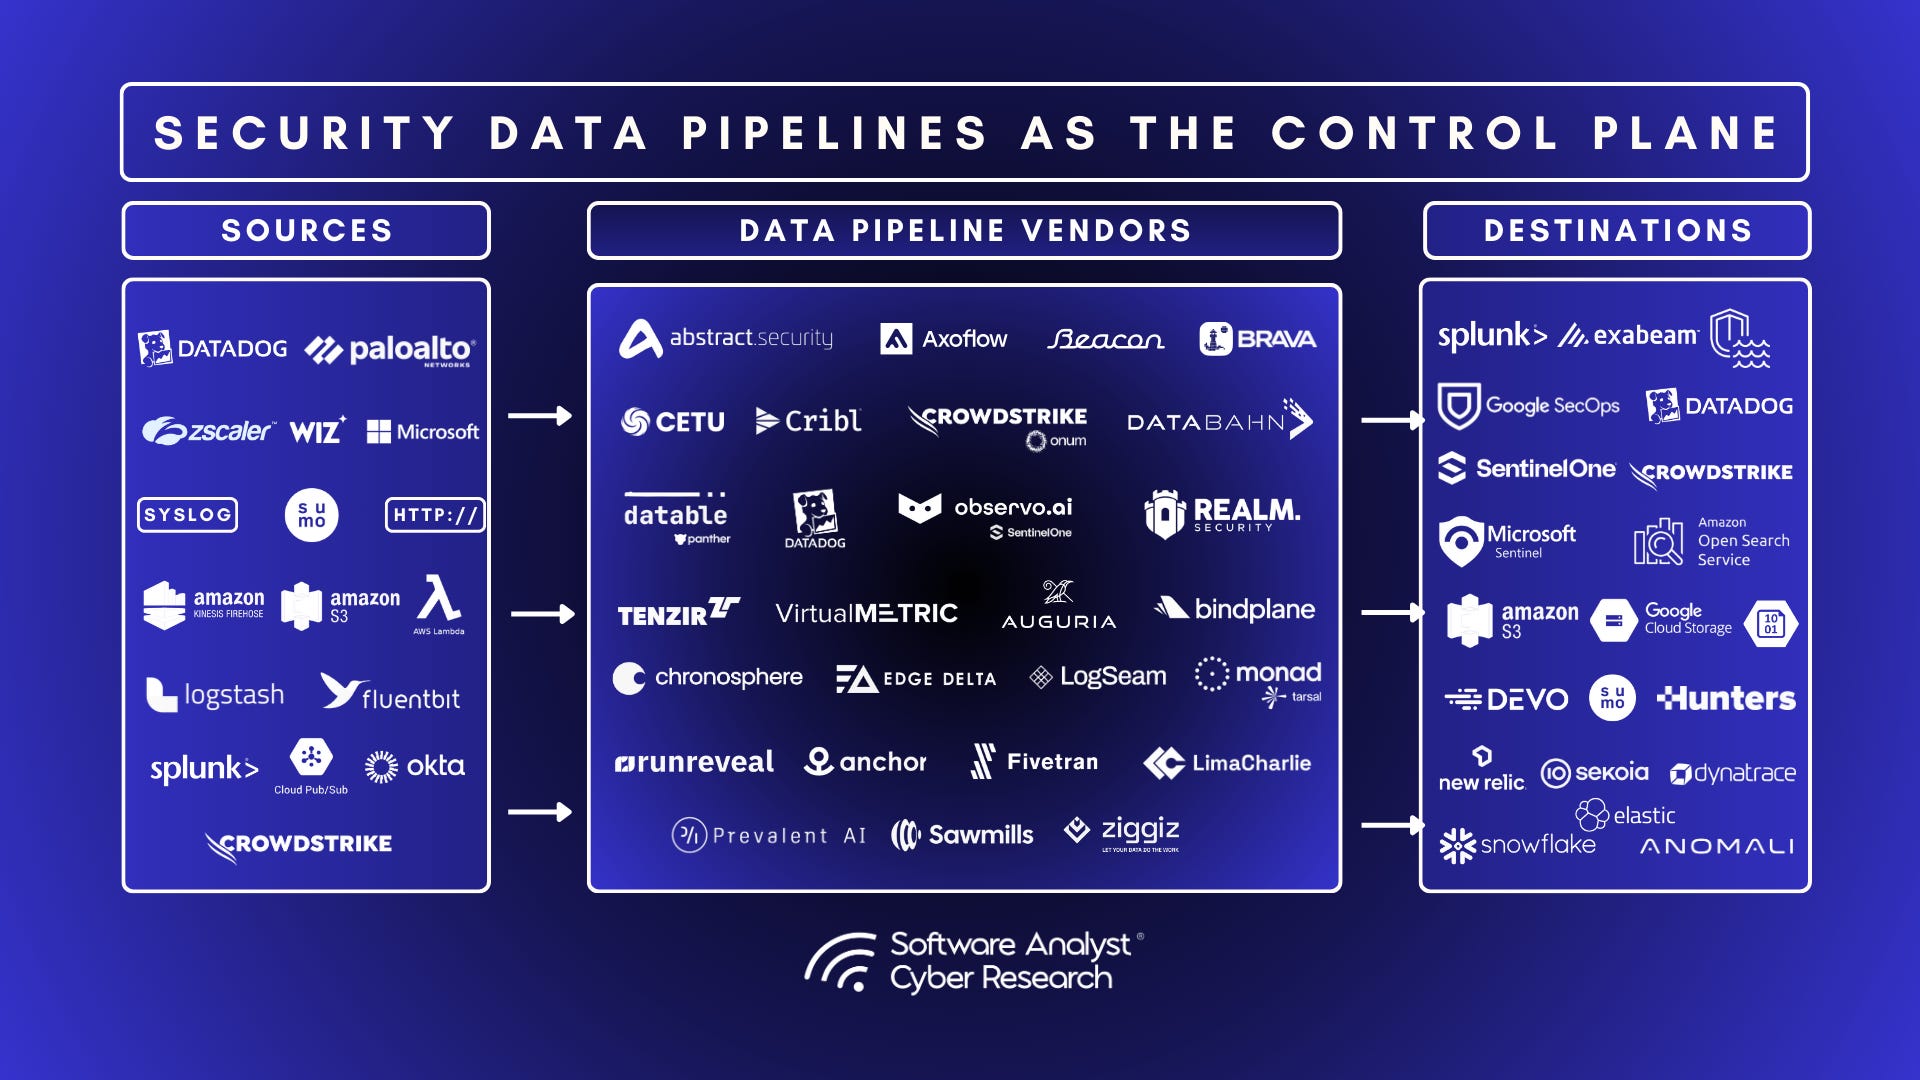
Automated Data Collection: Tools, Methods & Best Practices - What Is Automated Data Collection?.
Automated data collection is the use of software to capture, process, and store data from multiple sources without continuous human input. Instead of an analyst exporting a report by hand, a pipeline extracts records from databases, APIs, web pages, forms, and cloud services, cleans them, and loads them into a warehouse or analytics tool.
It typically covers four stages:
According to IBM's overview of data automation, a large share of organizational data is never analyzed at all, which is exactly the gap automation is meant to close. When collection is manual, data goes stale before anyone acts on it.
Automated Data Collection: Tools, Methods & Best Practices - Why Manual Collection Breaks Down.
The case for automation is not just speed. Manual collection introduces three compounding problems:
Research compiled by Nutshell highlights how much time sales teams lose to manual entry and CRM upkeep, and how automation shifts that time toward higher-value work. The same logic applies to research, pricing intelligence, and lead generation.
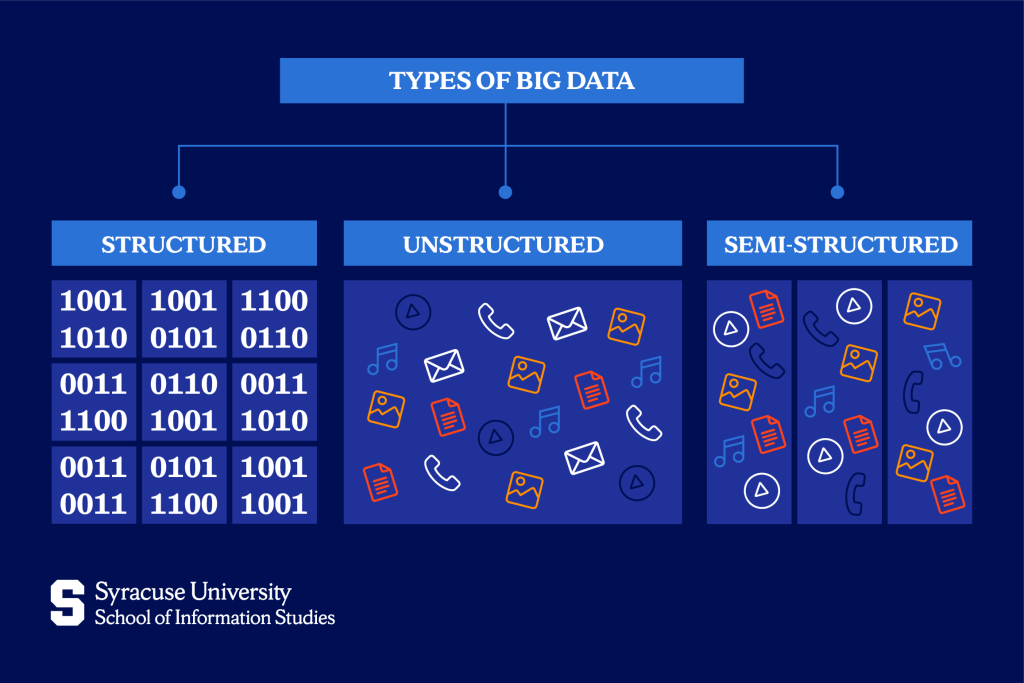
Automated Data Collection: Tools, Methods & Best Practices - Types of Data You Will Collect.
Not all data behaves the same way, and the collection method depends heavily on format.
Structured data follows a predefined format — database tables, spreadsheets, JSON responses from APIs. It is searchable and processable with standard tools.
Unstructured data has no fixed schema: page text, images, video, call recordings, PDFs. Collecting it at scale usually requires natural language processing, OCR, or image recognition on top of the collection layer.
HTML pages, emails, and log files fall in between. They have patterns, but those patterns change without warning — which is why scrapers need maintenance.
Automated Data Collection: Tools, Methods & Best Practices - Automated Data Collection Methods Compared.
| Method | Best for | Main trade-off |
|---|---|---|
| Web scraping APIs | High-volume, recurring extraction | Cost scales with volume; anti-bot handling varies |
| No-code scrapers | Non-technical users, simple sites | Limited flexibility on complex or protected sites |
| Browser automation (RPA) | Logged-in workflows, multi-step tasks | Fragile when UI changes |
| APIs and connectors | First-party and partner data | Restricted to what the provider exposes |
| Pre-built datasets | Bulk research without building scrapers | Not real-time; coverage limits |
| Data enrichment APIs | Appending context to existing records | Accuracy depends on the provider |
Scraper APIs provide programmatic access to prebuilt infrastructure and handle IP blocking, CAPTCHAs, and JavaScript rendering. They suit teams that need repeatable, scheduled extraction at scale.
Visual tools let users point and click to map fields, handle pagination, and schedule runs. They lower the technical barrier but often struggle with heavily protected or highly dynamic sites.
Robotic process automation performs repetitive tasks inside a browser — logging in, navigating, filling forms, exporting reports. This is where data collection overlaps with account-based operations, because many targets require an authenticated session.
When a provider exposes an official API, that is almost always the cleanest path. The limitation is coverage: you only get what the provider chooses to expose.
Platforms like Kaggle and Common Crawl offer bulk data without building a pipeline. Enrichment APIs append firmographic, contact, or location details to records you already have. AIMultiple's review of data collection automation tools covers the current landscape, including how MCP-native scraping is changing how AI agents call extraction tools.
Most collection guides stop at tool selection. In practice, the failure point is almost always access.
Modern platforms detect automation through browser fingerprints, behavioral signals, IP reputation, and account linkage. When you run dozens of collection sessions from one machine, platforms can associate those sessions with each other — and block or ban them as a group.
This is where an anti-detect browser becomes part of the collection stack rather than a separate concern. Tools like AdsPower create isolated browser environments, each with its own fingerprint signals (Canvas, WebGL, User Agent) and proxy configuration, so separate collection identities do not bleed into one another. For teams running multi-account research, affiliate campaigns, or logged-in scraping, that isolation is what keeps sessions stable.
Practical setup considerations:
If you are configuring proxy-backed profiles for the first time, the AdsPower and Proxy-Seller setup guide walks through proxy selection, profile configuration, and connection verification.
Collection volume is worthless if the data is wrong. Build these checks into the pipeline:
Automated collection sits in a legal grey zone depending on jurisdiction, target, and data type. Before scaling, confirm:
Collecting publicly available, non-personal data for research or price monitoring carries different risk than harvesting personal profiles. Treat compliance as a design requirement, not an afterthought.
Use this decision path:
For teams comparing isolation tools, the AdsPower vs Maskfog vs Dolphin Anty comparison breaks down fingerprint isolation, automation support, and pricing side by side.
It is using software to gather and organize data from sources like websites, APIs, and databases without someone manually copying it. The software handles extraction, cleaning, and delivery to wherever the data is needed.
No. Web scraping is one method of collection. Automated data collection also includes API integrations, ETL pipelines, form capture, and enrichment services.
Common causes include IP reputation, shared browser fingerprints, request rates that exceed normal human behavior, and missing or inconsistent session signals. Isolation and proxy quality address most of these.
Only if your collection requires authenticated sessions, multiple accounts, or targets with strong anti-bot detection. For public, unauthenticated pages, a scraper API is usually enough.
Validate against a schema on ingest, deduplicate on key fields, timestamp every record, and audit a sample regularly. Automation removes transcription errors but does not remove logic errors.
Automated data collection is less about picking a scraper and more about building a pipeline that survives contact with real targets. Start with the simplest method that works — an API if one exists — and add complexity only when access, scale, or account isolation demands it.
The teams that collect reliably are the ones that treat identity, proxies, and rate limits as first-class parts of the pipeline rather than obstacles to work around.


