
AdsPower vs ClonBrowser: Which Anti-Detect Browser Wins?
Nov 18, 2026
Web scraping is essential for market research, price monitoring, and lead generation. But modern websites fight back with IP blocks, CAPTCHAs, and browser fingerprinting. That’s where AdsPower (a professional anti-detect browser) and Beautiful Soup (a Python HTML parsing library) come together. This guide shows you how to combine these tools for anonymous, scalable, and maintainable scraping workflows.
AdsPower + Beautiful Soup: Web Scraping Guide 2026 product interface and feature overview.
AdsPower creates isolated browser environments with unique digital fingerprints. It lets you manage multiple accounts or scraping sessions without being detected. Beautiful Soup, on the other hand, is the go-to Python library for extracting structured data from HTML and XML. Together, they solve two core problems:
This combination is ideal for cross-border e-commerce sellers, affiliate marketers, and data analysts who need to scrape platforms like Amazon, Facebook, or Google without triggering bans.
AdsPower + Beautiful Soup: Web Scraping Guide 2026 product interface and feature overview.
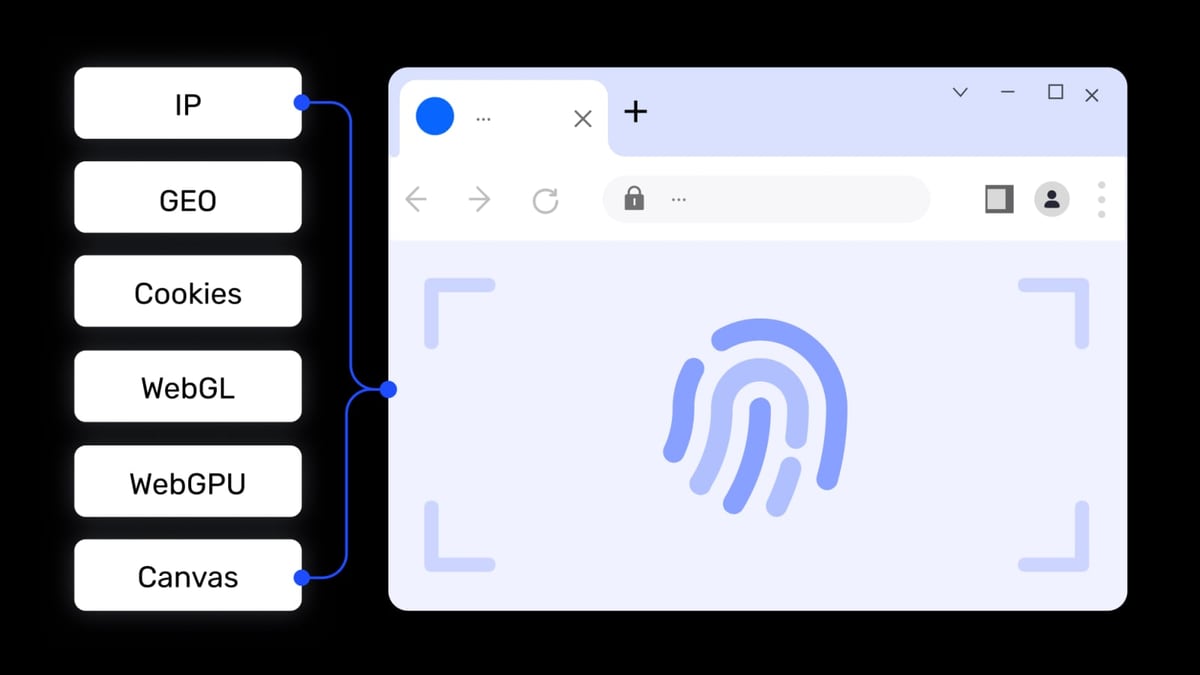
AdsPower + Beautiful Soup: Web Scraping Guide 2026 product interface and feature overview.
requests, beautifulsoup4, and selenium installed.Open AdsPower and click New Browser. Configure:
After creation, note the Environment ID (a 32-character hex string) – you’ll need it for the API.
AdsPower provides a REST API to open browser windows. Use this Python script to start an environment:
import requests
import json

# AdsPower Local API endpoint
url = "http://local.adspower.net:50325/api/v1/browser/start"

# Your environment ID
env_id = "YOUR_ENVIRONMENT_ID"

params = {
    "user_id": env_id,
    "open_urls": "https://example.com"  # optional
}

response = requests.get(url, params=params)
data = response.json()

if data["code"] == 0:
    print("Browser started successfully")
    print("WebSocket debugger URL:", data["data"]["ws"]["selenium"])
else:
    print("Error:", data["msg"])
AdsPower returns a WebSocket debugger URL that you can use with Selenium’s Remote driver:
from selenium import webdriver
from selenium.webdriver.chrome.options import Options

chrome_options = Options()
chrome_options.add_experimental_option("debuggerAddress", "127.0.0.1:9222")  # port from API response

driver = webdriver.Chrome(options=chrome_options)
driver.get("https://example.com")
Note: The exact port is provided in the API response under
data.data.ws.selenium. You may need to parse it.
Once the page loads, grab the HTML and let Beautiful Soup work its magic:
from bs4 import BeautifulSoup

html = driver.page_source
soup = BeautifulSoup(html, "html.parser")

# Example: extract all product titles
titles = soup.find_all("h2", class_="product-title")
for title in titles:
    print(title.get_text(strip=True))
Always close the browser to free resources:
requests.get("http://local.adspower.net:50325/api/v1/browser/stop", params={"user_id": env_id})
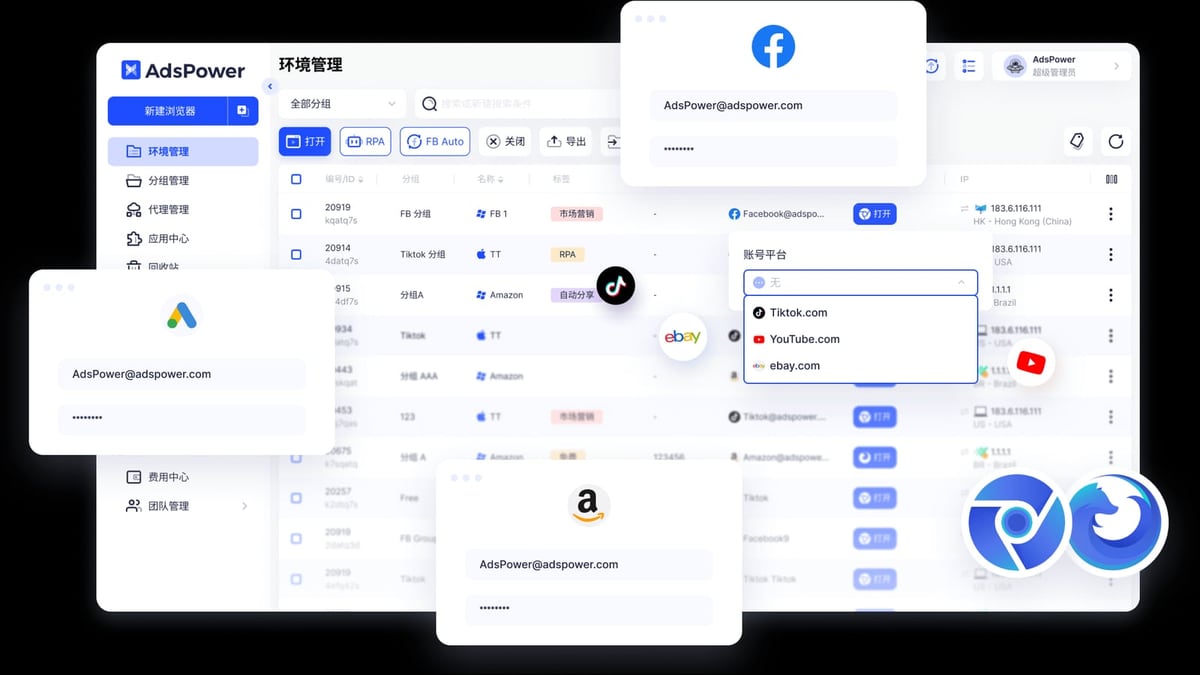
AdsPower + Beautiful Soup: Web Scraping Guide 2026 product interface and feature overview.
Let’s say you want to monitor prices on an e-commerce site. Here’s a complete script that uses AdsPower for anonymity and Beautiful Soup for parsing:
import requests
from selenium import webdriver
from bs4 import BeautifulSoup

# Start AdsPower environment
env_id = "abc123..."
start_resp = requests.get("http://local.adspower.net:50325/api/v1/browser/start",
                          params={"user_id": env_id, "open_urls": "https://shop.example.com/products"})
data = start_resp.json()

# Connect Selenium
debugger_url = data["data"]["ws"]["selenium"]
chrome_options = webdriver.ChromeOptions()
chrome_options.add_experimental_option("debuggerAddress", debugger_url.split(":")[-1])
driver = webdriver.Chrome(options=chrome_options)

# Wait for page load (use explicit waits in production)
import time
time.sleep(3)

# Parse with Beautiful Soup
soup = BeautifulSoup(driver.page_source, "html.parser")
prices = []
for item in soup.select(".product-card"):
    name = item.find("h3").get_text(strip=True)
    price = item.find("span", class_="price").get_text(strip=True)
    prices.append({"name": name, "price": price})

print(prices)

# Cleanup
driver.quit()
requests.get("http://local.adspower.net:50325/api/v1/browser/stop", params={"user_id": env_id})
AdsPower lets you create hundreds of environments, each with a unique fingerprint and proxy. To scrape at scale:
Example snippet using concurrent.futures:
from concurrent.futures import ThreadPoolExecutor

def scrape_env(env_id, proxy, url):
    # Launch, scrape, parse, close
    pass

with ThreadPoolExecutor(max_workers=5) as executor:
    executor.map(scrape_env, env_ids, proxies, urls)
| Problem | Solution |
|---|---|
| AdsPower API returns "port already in use" | Close unused environments or increase the port range in AdsPower settings. |
| Beautiful Soup can’t find elements | Check if the content is loaded via JavaScript. Use Selenium’s WebDriverWait before parsing. |
| Websites still block requests | Ensure your proxy is clean and not blacklisted. Consider rotating proxies per environment. |
| Selenium driver version mismatch | Match your ChromeDriver version to the Chromium version used by AdsPower (SunBrowser). |
Yes, if the target page is static. You can use requests inside the AdsPower environment by setting the same proxy and user-agent. However, most modern sites require JavaScript rendering, so Selenium is recommended.
The free tier includes 2 browser environments. For small-scale scraping, it’s sufficient. For larger projects, consider a paid plan that supports more environments and team collaboration.
Absolutely. AdsPower’s Local API also returns WebSocket URLs compatible with Playwright and Puppeteer. The same Beautiful Soup logic applies.
AdsPower’s fingerprint isolation reduces CAPTCHA triggers, but you may still encounter them. Integrate a CAPTCHA-solving service (e.g., 2Captcha) in your Selenium flow.
Combining AdsPower with Beautiful Soup gives you a powerful, anonymous web scraping stack. AdsPower handles fingerprint diversity and proxy management, while Beautiful Soup makes HTML parsing a breeze. Whether you’re scraping product data, monitoring competitors, or aggregating leads, this duo lets you scale without getting blocked.
Start with the free tier of AdsPower, experiment with the code examples above, and gradually expand to multi-environment scraping. For more comparisons of anti-detect browsers, check out our AdsPower vs Indigo vs GoLogin guide or learn how to integrate AdsPower with Bright Data for even better proxy management.
Happy scraping – and stay undetected!


