
AdsPower vs ClonBrowser: Which Anti-Detect Browser Wins?
Nov 18, 2026
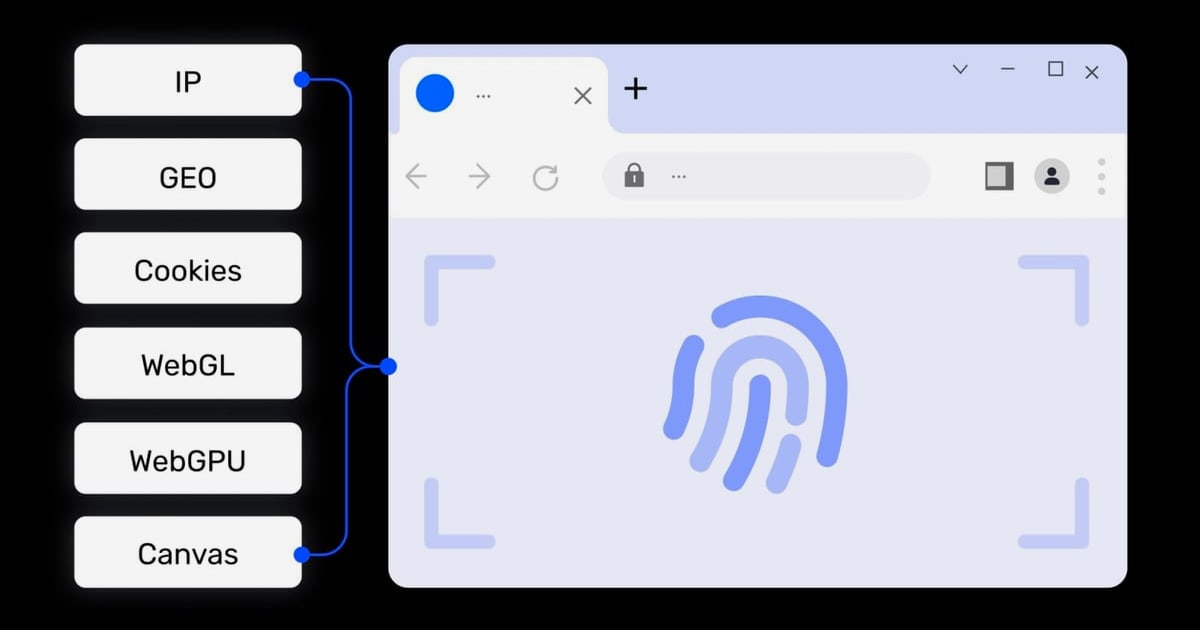
Web scraping at scale often triggers anti-bot measures that block or fingerprint your scraper. Combining AdsPower fingerprint browser with Scrapy gives you a powerful, stealthy scraping pipeline. AdsPower provides isolated browser environments with unique digital fingerprints, while Scrapy handles the crawling and data extraction. Together, they solve account association, IP blocking, and browser fingerprint detection.
This guide walks through the integration workflow, setup steps, practical code examples, and the specific problems this combination solves.
How to Use AdsPower Fingerprint Browser with Scrapy product interface and feature overview.
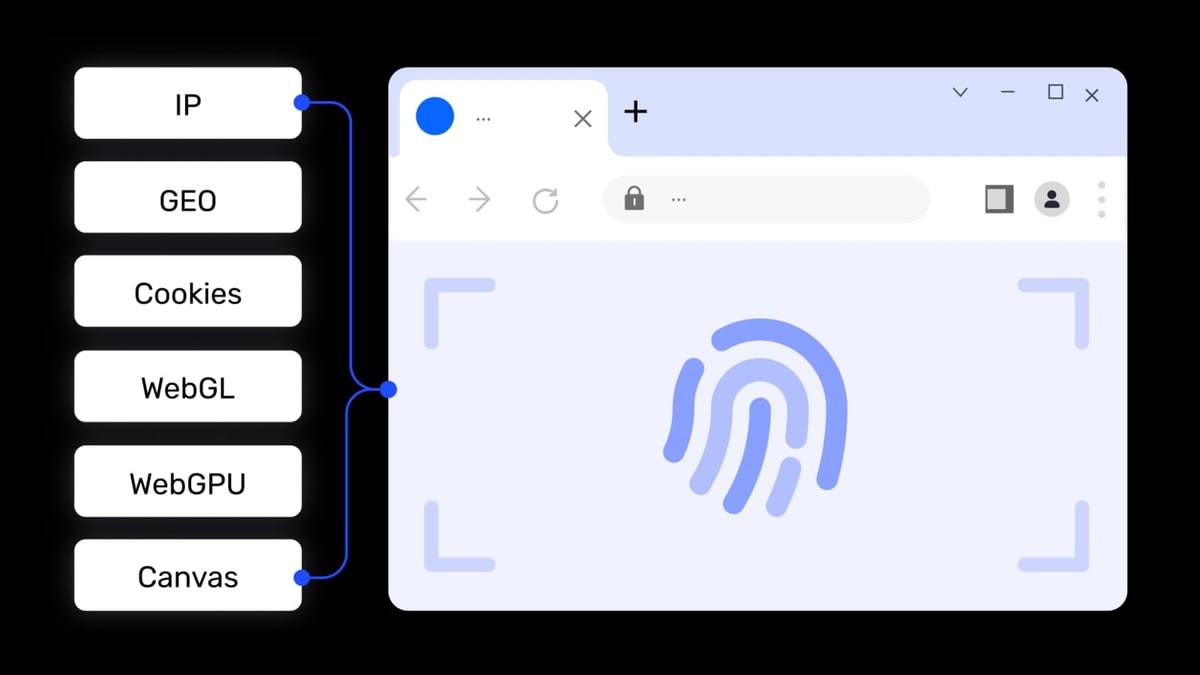
Scrapy is a fast, asynchronous Python framework for extracting data from websites. However, it uses raw HTTP requests by default, which makes it easy for sites to detect and block scrapers. AdsPower creates real browser environments with customizable fingerprints (Canvas, WebGL, Audio, WebRTC, etc.), making each session appear as a unique user on a different device.
Problems solved by this combination:
How to Use AdsPower Fingerprint Browser with Scrapy product interface and feature overview.
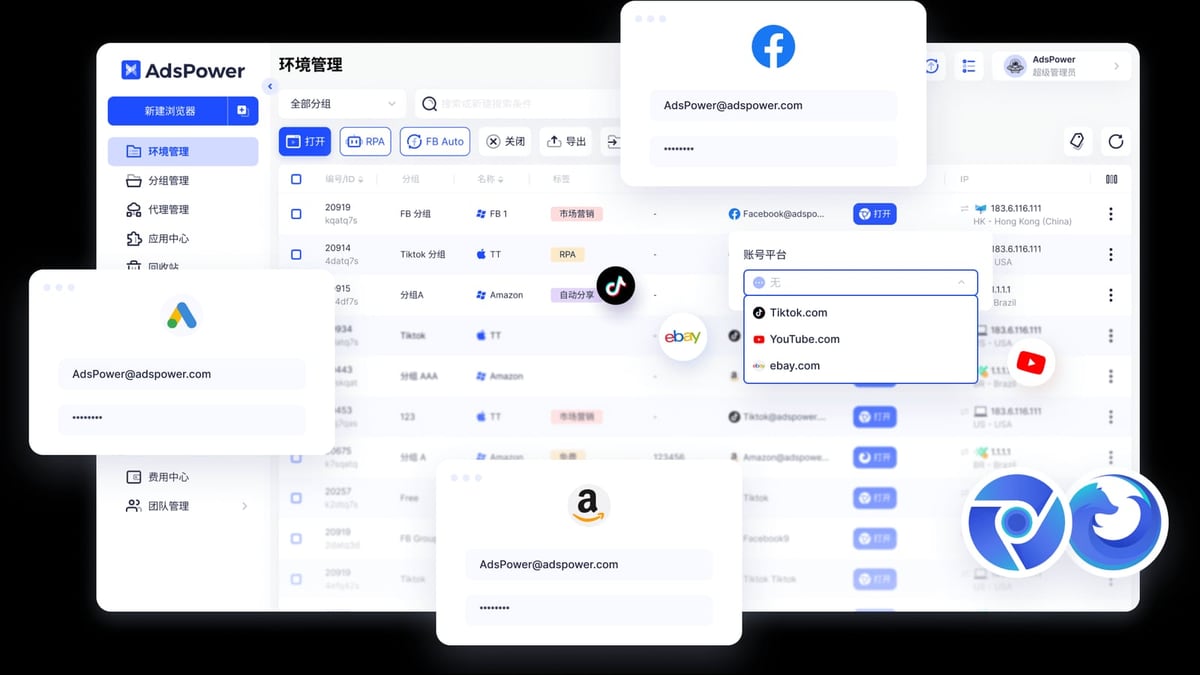
The workflow has three main components:
Here’s the high-level flow:
How to Use AdsPower Fingerprint Browser with Scrapy product interface and feature overview.
Before you start, ensure you have:
pip install scrapypip install requests
How to Use AdsPower Fingerprint Browser with Scrapy product interface and feature overview.
Open AdsPower, go to Settings > API, and note the API port (default is 50325). Keep the AdsPower client running in the background.
In AdsPower, create a new browser profile. Assign a proxy (HTTP, HTTPS, SOCKS5) if needed. Note the user_id of the profile – you’ll use it in API calls.
pip install scrapy
scrapy startproject adspower_scraper
cd adspower_scraper
Create a file adspower_api.py in your project folder:
import requests

API_BASE = "http://127.0.0.1:50325"

def start_browser(user_id):
    url = f"{API_BASE}/api/v1/browser/start"
    params = {"user_id": user_id}
    response = requests.get(url, params=params)
    data = response.json()
    if data["code"] != 0:
        raise Exception(f"Failed to start browser: {data['msg']}")
    return data["data"]["debug_port"]

def close_browser(user_id):
    url = f"{API_BASE}/api/v1/browser/stop"
    params = {"user_id": user_id}
    requests.get(url, params=params)
Here’s a spider that scrapes a target URL using a browser environment started by AdsPower:
import scrapy
from scrapy.http import HtmlResponse
from selenium import webdriver
from selenium.webdriver.chrome.options import Options
from .adspower_api import start_browser, close_browser

class AdspowerSpider(scrapy.Spider):
    name = "adspower_spider"
    allowed_domains = ["example.com"]
    start_urls = ["http://example.com"]

    def __init__(self, user_id=None, *args, **kwargs):
        super().__init__(*args, **kwargs)
        self.user_id = user_id or "your_user_id_here"

    def start_requests(self):
        # Start the AdsPower browser profile
        debug_port = start_browser(self.user_id)
        self.logger.info(f"Browser started on debug port {debug_port}")

        # Connect Selenium to the existing browser
        chrome_options = Options()
        chrome_options.add_experimental_option("debuggerAddress", f"127.0.0.1:{debug_port}")
        driver = webdriver.Chrome(options=chrome_options)

        for url in self.start_urls:
            driver.get(url)
            body = driver.page_source
            response = HtmlResponse(url=url, body=body, encoding='utf-8')
            yield response

        driver.quit()
        close_browser(self.user_id)

    def parse(self, response):
        # Extract data using Scrapy selectors
        title = response.css('title::text').get()
        yield {"title": title}
scrapy crawl adspower_spider -a user_id=YOUR_USER_ID
Let’s scrape product prices from an e-commerce site that uses fingerprinting.
start_urls with the product URL.parse(), extract price, name, and availability.def parse(self, response):
product_name = response.css('h1.product-title::text').get()
price = response.css('span.price::text').get()
yield {
"name": product_name,
"price": price,
"url": response.url
}
Each spider run uses a fresh browser fingerprint, making the request appear as a new visitor.
For sites with heavy JavaScript, use Playwright instead of Selenium:
from playwright.sync_api import sync_playwright

def fetch_page(url, debug_port):
    with sync_playwright() as p:
        browser = p.chromium.connect_over_cdp(f"http://127.0.0.1:{debug_port}")
        page = browser.new_page()
        page.goto(url)
        content = page.content()
        browser.close()
        return content
Then call this from your spider’s start_requests.
| Problem | Solution |
|---|---|
| API returns error code | Ensure AdsPower client is running and API port is correct |
| Browser doesn’t close | Call close_browser() in spider’s closed() method |
| Fingerprint still detected | Update AdsPower to latest version; check fingerprint spoofing settings |
| Proxy not working | Verify proxy format in AdsPower profile (HTTP/SOCKS5) |
Yes. Start each profile with a unique user_id and manage them in parallel using Scrapy’s CONCURRENT_REQUESTS setting.
The free tier includes 2 browser environments, which is enough for testing. For production scraping with many profiles, consider a paid plan.
Create multiple AdsPower profiles with different fingerprints. In your spider, cycle through user_id values for each request.
AdsPower’s fingerprint spoofing significantly reduces detection risk, but no method is 100% undetectable. Always respect robots.txt and terms of service.
Integrating AdsPower fingerprint browser with Scrapy creates a robust scraping setup that bypasses browser fingerprinting and account association detection. By using AdsPower’s Local API to launch isolated browser environments, your Scrapy spiders can scrape data stealthily at scale.
For more on anti-detect browsers, check our AdsPower vs Undetectable comparison. If you’re new to AdsPower automation, our guide on using AdsPower with Python covers the basics.
Start with a free AdsPower account and a simple Scrapy spider. Test on a low-risk site, then scale up as you gain confidence.


